Market value
What the questions you track are worth, how much of that market they reach, and how much of it names you.
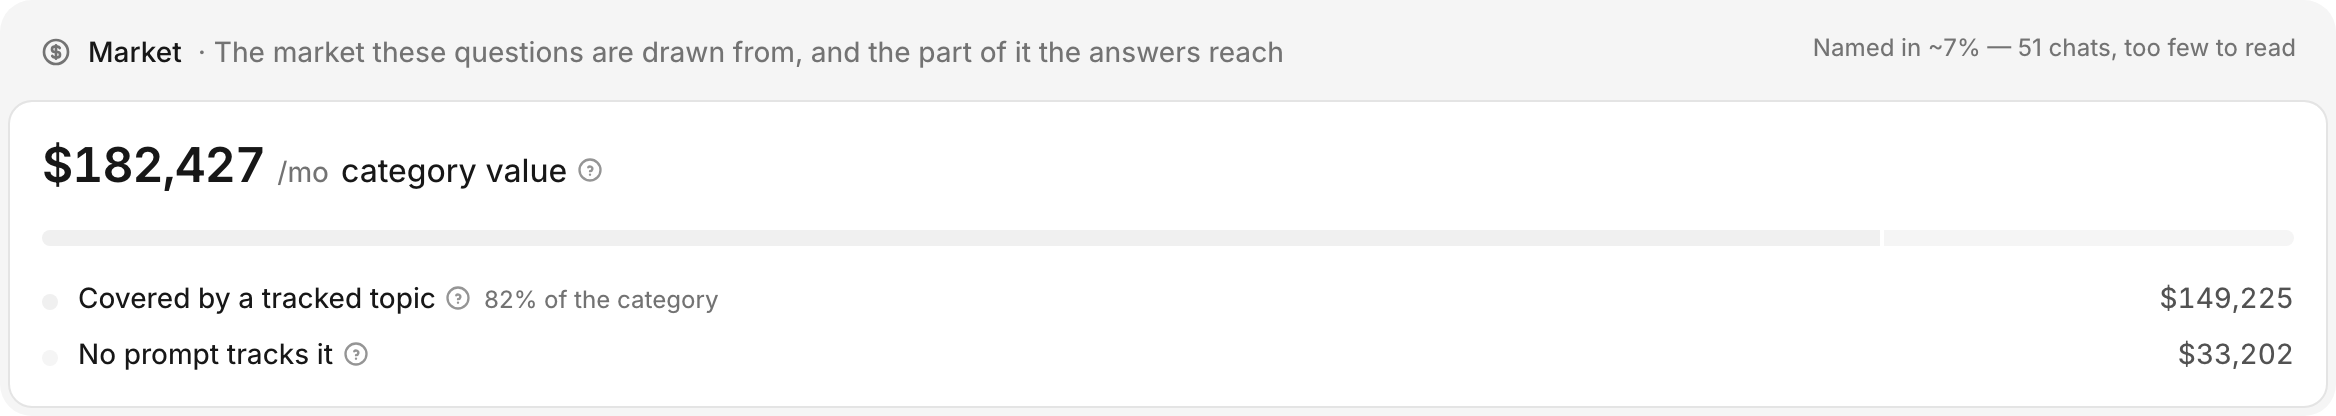
The four brand metrics say how a chat treated you. None of them says whether the chat was worth being in. Market value is the denominator: what the intents behind your prompt set are worth per month, how much of that a tracked question reaches at all, and how much of that the models name you in.
category value   what the market pays, per month, to own these intents
prompt coverage  the share of it any tracked topic reaches
captured         the share of what is covered that the answers name you in
Three figures, deliberately not one. A brand can be highly visible on a corner of its category worth very little, and the four brand metrics will report that as success.
The pool
Every figure here is arithmetic over one table: the pool, the set of keywords the category is actually contested on. It is rebuilt monthly, kept as a numbered version, and you can read every row of it on Keywords.
It is built from what you and your tracked competitors already rank for, in seven steps:
| # | The cut | Why |
|---|---|---|
| 1 | Every keyword you or a rival ranks in the top 20 for | Below that, a ranking is not evidence of anything |
| 2 | Brand terms removed — your names, aliases and domains, and theirs | “acme pricing” is your own traffic, not the category’s |
| 3 | Only keywords at least two of those domains rank for | One site ranking alone is that site’s content marketing |
| 4 | Only commercial and transactional intent | An informational keyword answers with a paragraph naming nobody |
| 5 | Near-identical variants collapsed into one row | The vendor lists “usage based billing” and its plural separately |
| 6 | Each keyword priced (below) | — |
| 7 | Cut at 95% of the total value | The long tail adds rows and no money |
Steps 1 and 3 are the ones doing the work. Take a large rival’s thousand biggest keywords by volume and you get that rival’s blog: for a billing product, the top of the list comes back “purchase orders”, “llc registration”, “business credit cards”. Requiring a top-20 ranking from two different domains is what makes the same query answer about the category.
How a keyword is priced
value = monthly searches × 0.3 × cost per click- Monthly searches — Google’s volume for the keyword in the project’s country. Not how often it is asked of an assistant, which is a different quantity nobody publishes.
- 0.3 — roughly the share of clicks the top organic result takes. Without it the figure answers “what would it cost to buy every click for this keyword”, which is an advertising budget and not the value of owning the intent — a difference of two orders of magnitude on a mid-sized category.
- Cost per click — what advertisers bid, from Google Ads.
What CPC is taken to mean here
A bid is the market’s own price on an intent, not the price of Google traffic. An advertiser paying $18 for “best billing software” is telling you what that buyer is worth to them, and that is true whichever interface eventually answers the question. What a bid is not is your revenue: being named in an answer is not a click.
That is also why the money and the percentages are never multiplied together. The product says what share of a priced market the answers name you in; it never prints a dollar figure for what you captured, because that number would be a claim about clicks nobody counted.
Prompt coverage
prompt coverage = value of keywords a tracked topic reaches ÷ value of the whole poolOnce the pool is priced, a model places each keyword onto one of your topics, or onto none. Coverage is the share of the money that landed on a topic you actually ask questions about. The rest is uncovered: real demand in your category that no question measures, so you are scored on it in neither direction.
The denominator is the whole pool, including the uncovered part. Adding prompts raises coverage; it never quietly enlarges the market to match what you happen to track. That is what makes one month’s figure comparable with the next, which is the only reason to have the figure.
Captured
captured = Σ (topic value × that topic's visibility) ÷ Σ (value of the measured topics)Visibility with each topic weighted by what it is worth, rather than every question counted once. A brand winning the cheap questions and losing the expensive one reads as doing badly here — which is the entire point of the figure.
Two things are held out of it deliberately:
- A priced topic nobody has sampled yet is in neither the numerator nor the denominator. Folding it in as 0% would report a measurement that was never taken.
- A reading carried by thin topics is not reported. More than half the value in the average has to come from topics that individually clear the sample floor. Summing sample sizes across topics hid exactly this: 51 answers spread over four topics, none of them readable on its own, presented as a reading. A weighted average is only as sound as the weights carrying it.
When a figure is missing
Three different absences, and none of them is a zero:
| You see | It means |
|---|---|
| No Market panel at all | No pool has been built for this project yet |
Coverage as — | The pool is priced but not yet placed onto topics |
| Captured absent, with a note | No answers against a priced topic yet, or too few to read |
A pool that has been priced but not placed has every keyword sitting in the uncovered bucket, so the arithmetic would return 0% coverage — a sentence telling a brand it reaches none of its market, produced by a job that has not finished. The product says which of the three it is instead.
What this is not
It is not total category demand. The pool is defined by what you and your rivals rank for, so it measures the market somebody is contesting. Rivals with weak SEO make for a smaller pool. That is the right frame for a competitive gap and the wrong one for a market-sizing slide.
It is not everything you track. Plenty of good prompts have no priced demand behind them — a subject buyers ask assistants about and nobody bids on. Those topics are still measured by the four brand metrics; they simply carry no money, and the product says “not priced” rather than “worth nothing”.
It is not deeper than one page per domain. Sampling three times as many keywords per rival was tested: the contested set grew in exact proportion, the number of topics with a price behind them barely moved, and on one project coverage fell — a deeper sample mostly adds the rivals’ wider tail, which is further from the subjects you track. What the contested cut removes is real.